# Instagram Scraper - Posts, Reels, Hashtags & Profiles (`topapi/instagram-scraper`) Actor

Scrape Instagram posts and reels by profile, hashtag or URL: caption, likes, comments, plays and views on every reel, engagement rate, date, media URLs, music, tagged users, location, latest comments. Reels tab mode, date and type filters, monitor mode with play-count deltas. No login.

- **URL**: https://apify.com/topapi/instagram-scraper.md
- **Developed by:** [Top Api](https://apify.com/topapi) (community)
- **Categories:** Social media, Marketing, Lead generation
- **Stats:** 172 total users, 106 monthly users, 100.0% runs succeeded, 1 bookmarks
- **User rating**: No ratings yet

## Pricing

from $0.40 / 1,000 post scrapeds

This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.

Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event

## What's an Apify Actor?

An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.

Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.

## How to integrate an Actor?

If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.

Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.

For examples already wired to this Actor's own input schema, see the [API](#api) section below.

Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).

# README

### What does Instagram Scraper do?

**Instagram Scraper** extracts Instagram posts and reels from instagram.com and turns profile names, hashtags or post URLs into structured rows: one row per post, reel or carousel with caption, likes, comments, plays, views, publish date, media URLs, music, tagged users and the owner. Built for marketing teams, influencer and brand researchers, and data pipelines that need Instagram posts and reels data without a login, cookies or an API key.

Instagram Posts Scraper - Instagram Reels Scraper - Instagram Hashtag Scraper - Instagram Profile Posts API

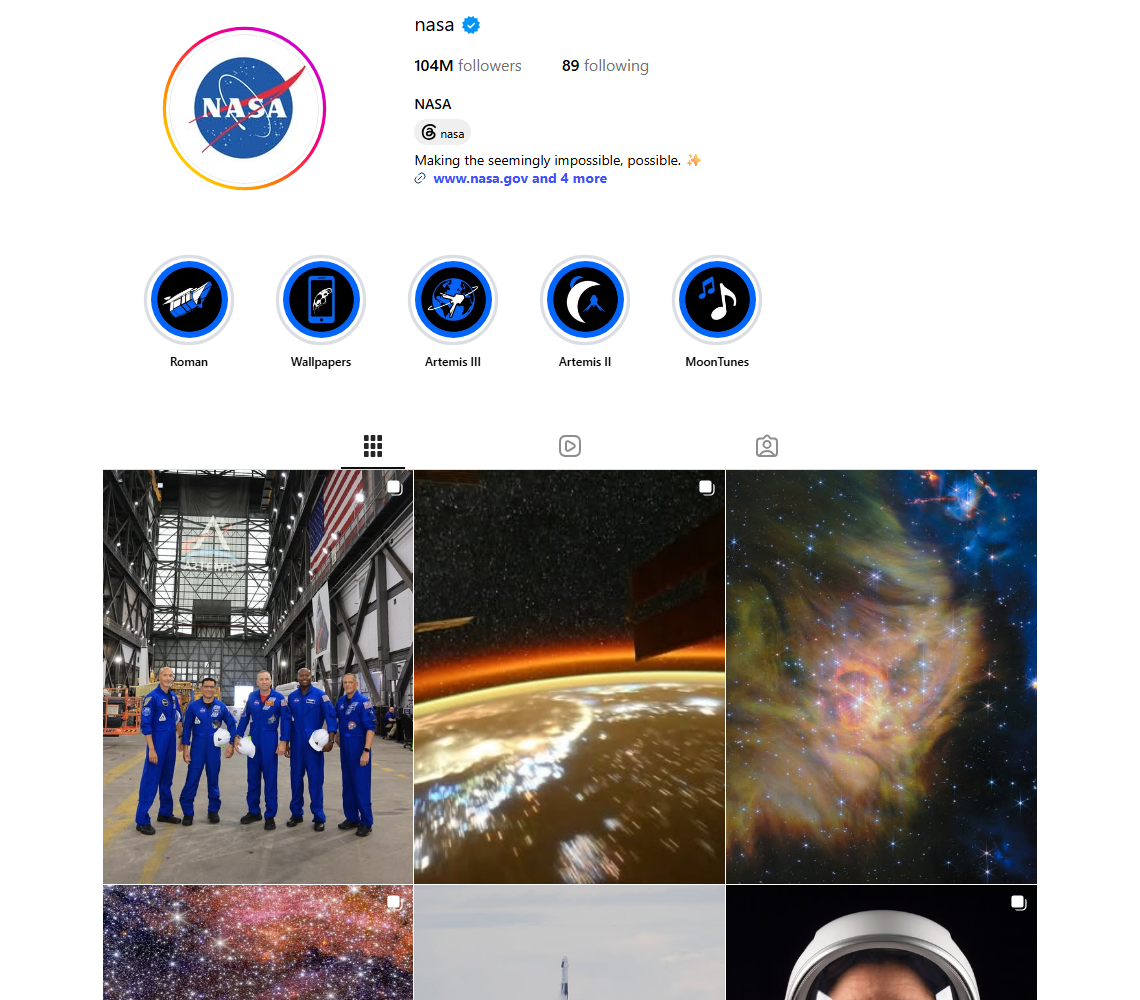
<a href="https://console.apify.com/actors/5UGcwS9WCCJbVqzDY"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/instagram-scraper-source.png" alt="Instagram posts grid of a public profile that Instagram Scraper turns into rows" style="width:70%"></a>

- **Every reel of a profile, with plays on every row:** set **Content** to **Reels** and the actor reads the profile's Reels tab (also reels that are not in the grid), with play, like and comment counts on each reel.
- **Posts, reels and carousels** from any public profile (newest first, pinned flagged), **hashtags and keywords** (Instagram's public keyword page) and **single posts or reels by URL**.
- **Views and plays, both:** `videoViewCount` next to `videoPlayCount` on every video and reel, plus `playsPerFollower` and `engagementRate`.
- **Reel growth tracking:** with `monitorDelivery: "changes"` a scheduled run returns only the reels whose plays, likes or comments moved, with the deltas.
- **Latest comments** with one switch, the audio-only `audioUrl` of each reel, every image rendition, carousel items with their own tagged users.
- **No login, cookies or Instagram API key:** the actor reads only what Instagram shows a signed-out visitor.
- **Filters:** date window, content type, minimum likes or plays, keyword, tagged place, pinned posts; pay-per-result with no start fee.
- **Export anywhere:** JSON, CSV, Excel; schedules, webhooks, Make, Zapier, n8n, Google Sheets; the API and MCP for AI agents, with `compact` rows.

### What data can you get from Instagram?

<table>
<tr>
<td>🔗 Post URL and shortcode (`url`, `shortCode`)</td>
<td>📝 Caption, hashtags, mentions</td>
<td>📅 Publish date (`timestamp`)</td>
</tr>
<tr>
<td>❤️ Likes (`likesCount`)</td>
<td>💬 Comments count and latest comments</td>
<td>▶️ Reel plays (`videoPlayCount`)</td>
</tr>
<tr>
<td>👁️ Video views (`videoViewCount`)</td>
<td>📈 Engagement rate, plays per follower</td>
<td>📊 Play, like and comment deltas between runs</td>
</tr>
<tr>
<td>🖼️ Image URLs in every size (`displayUrl`, `images`)</td>
<td>🎬 Video URL, audio-only URL, duration</td>
<td>🎵 Sound: song, artist, original audio, trending</td>
</tr>
<tr>
<td>🏷️ Tagged users with positions</td>
<td>🤝 Co-authors and paid-partnership sponsors</td>
<td>📍 Location name, id, city, coordinates</td>
</tr>
<tr>
<td>🧩 Carousel items (`childPosts`)</td>
<td>📌 Pinned, type, product type (reel / feed / carousel)</td>
<td>👤 Owner username, name, id, verified, avatar, followers</td>
</tr>
</table>

On a live run of 4 profiles × 25 reels (2026-10-20) every one of the 100 reels had a caption, date, plays, views, likes, comments, video URL and duration; 98% had the audio-only URL and the sound, 71% tagged users, 42% co-authors and 18% a location.

### How to scrape Instagram with Instagram Scraper

1. [Create a free Apify account](https://console.apify.com/sign-up) - $5 of monthly credit, no card needed.
2. Open [Instagram Scraper](https://apify.com/topapi/instagram-scraper) and click **Try for free**.
3. Paste usernames into **Profiles**, hashtags into **Hashtags or keywords**, or links into **Post or reel URLs**. For a creator's reels set **Content** to **Reels**.
4. Set **Max posts per profile or hashtag** and click **Start**. Rows stream into the dataset as pages are read.
5. Open the **Storage** tab and **Export** as JSON, CSV or Excel - or let a schedule run it for you.

### ⬇️ Input

| Parameter | Type | Description |
|---|---|---|
| **🔍 What to scrape** | | |
| `usernames` | List | Usernames or profile URLs: `nasa`, `@natgeo`, `https://www.instagram.com/instagram/`. Default: `["nasa"]` when nothing else is given |
| `hashtags` | List | Hashtags or keywords: `travel`, `#foodie`, `https://www.instagram.com/explore/tags/travel/`. Read from Instagram's public keyword page |
| `postUrls` | List | Post or reel URLs or shortcodes: `https://www.instagram.com/p/Dd9RyBWBVih/`, `Dd9RyBWBVih` |
| `postType` (Content) | Select | `all`, `reel`, `video`, `image`, `carousel`. `reel` reads each profile's Reels tab; on hashtags and URLs it keeps reels only. Default: `all` |
| `dataDetailLevel` | Select | `detailedData` (caption, date, media, sound, tags + counts) or `basicData` (counts, cover and URL only, about 30× less data). Applies to Reels-tab and hashtag rows. Default: `detailedData` |
| **🎯 Filters** (decide how far back a profile is read) | | |
| `onlyPostsNewerThan` | String | `2026-09-01`, `7 days`, `3 weeks`, or a day count. Paging stops when a whole page is older |
| `onlyPostsOlderThan` | String | Upper bound of the window, same formats |
| `skipPinnedPosts` | Boolean | Leave out posts and reels pinned to the top of the grid or Reels tab. Default: `false` |
| **✂️ Refine results** | | |
| `minLikes` | Integer | Keep only posts with at least this many likes. Default: `0` |
| `minPlays` | Integer | Keep only reels with at least this many plays. Default: `0` |
| `keywordFilter` | String | Keep only posts whose caption, hashtags, tagged users, place, sound or owner contain the word(s); comma = any. Needs detailed data |
| `withLocationOnly` | Boolean | Keep only posts tagged with a place. Default: `false` |
| **➕ Extra data** | | |
| `includeVideoViewCount` | Boolean | Adds `videoViewCount` to every video and reel (one extra page per video, free). Default: `true` |
| `includeLatestComments` | Boolean | Adds `latestComments` (newest 12-15) and `firstComment` to every row with comments (one extra request per row, free). Default: `false` |
| `includeProfileSummary` | Boolean | Adds one `Profile` row per scraped profile - charged as **profile-summary** at $0.001 per profile |
| **🔁 Monitoring** | | |
| `monitorMode` | Boolean | Return only posts not delivered by previous runs; pair with a daily schedule |
| `monitorDelivery` | Select | `new` (new posts only) or `changes` (new posts + posts whose plays, likes or comments moved, with deltas). Default: `new` |
| `monitorStoreName` | String | Name of the key-value store holding the monitor memory. Default: `instagram-posts-monitor` |
| **📦 Output** | | |
| `resultsLimit` | Integer | Max posts per profile or hashtag after filters. Default `50`; `0` = everything Instagram serves |
| `maxItems` | Integer | Hard cap for the whole run. Default `0` = no total cap |
| `compact` | Boolean | Core fields only, sized for AI agents and MCP |
| **⚙️ Advanced** | | |
| `proxyConfiguration` | Object | Apify proxy settings. Default: Apify datacenter proxies, which serve every request this actor makes |
| `maxConcurrency` | Integer | Parallel per-post requests (details, views, comments, URLs). Default `4` |

#### Input JSON

A creator's reels from the last 30 days with plays, views and comments, plus a keyword and one reel URL:

```json
{
  "usernames": ["natgeo"],
  "hashtags": ["travel"],
  "postUrls": ["https://www.instagram.com/reel/Dd9RyBWBVih/"],
  "postType": "reel",
  "onlyPostsNewerThan": "30 days",
  "resultsLimit": 50,
  "includeLatestComments": true
}
```

#### Use Content = Reels when you want a creator's reels

The profile timeline mixes photos, carousels and the reels that are in the grid. **Reels** reads the profile's Reels tab instead: only reels, newest first (pinned reels first), including reels that are not shown in the grid, and the play count comes on every row from the same request. **Do:** `natgeo` in Profiles + Content `Reels` · **Don't:** Content `All posts` with a reels-only filter in mind (you would pay for reading photos you then drop).

#### Basic reel data for counting, detailed for everything else

`basicData` delivers each reel from the Reels tab or keyword page as it is: plays, likes, comments, cover, URL and owner id. It needs no extra request per reel, so 1,000 reels of a profile took 84 seconds and 85 requests in testing. It has no caption, date, media links or sound; use `detailedData` (the default) for those, and for `keywordFilter`.

#### Schedule it: new posts once, or reel growth with deltas

`onlyPostsNewerThan: "1 day"` on a profile reads one page and stops; with `monitorMode` on, a daily schedule delivers each post exactly once. With `monitorDelivery: "changes"` each run re-reads the newest reels (up to `resultsLimit`) and delivers only those whose plays, likes or comments moved, with `playCountDelta`, `likesDelta`, `commentsDelta`. In testing a run one minute after the first delivered 11 of 24 reels; the 13 that had not moved cost nothing. Pair it with `basicData` for the cheapest hourly tracker.

#### Hashtags are Instagram's public keyword page, not the signed-in hashtag feed

Signed-out visitors get a keyword page of popular reels for a term, 12 per page, in Instagram's ranking. It exists for many terms (`travel`, `foodie`, `street food`) and not for others (`sunset`, `coffee`, `nasa` returned no posts in testing); an empty term delivers nothing and says so in the run status.

### ⬆️ Output

Every post or reel becomes one dataset item. Here is the table view of a run for `nasa`, `travel` and one reel URL:
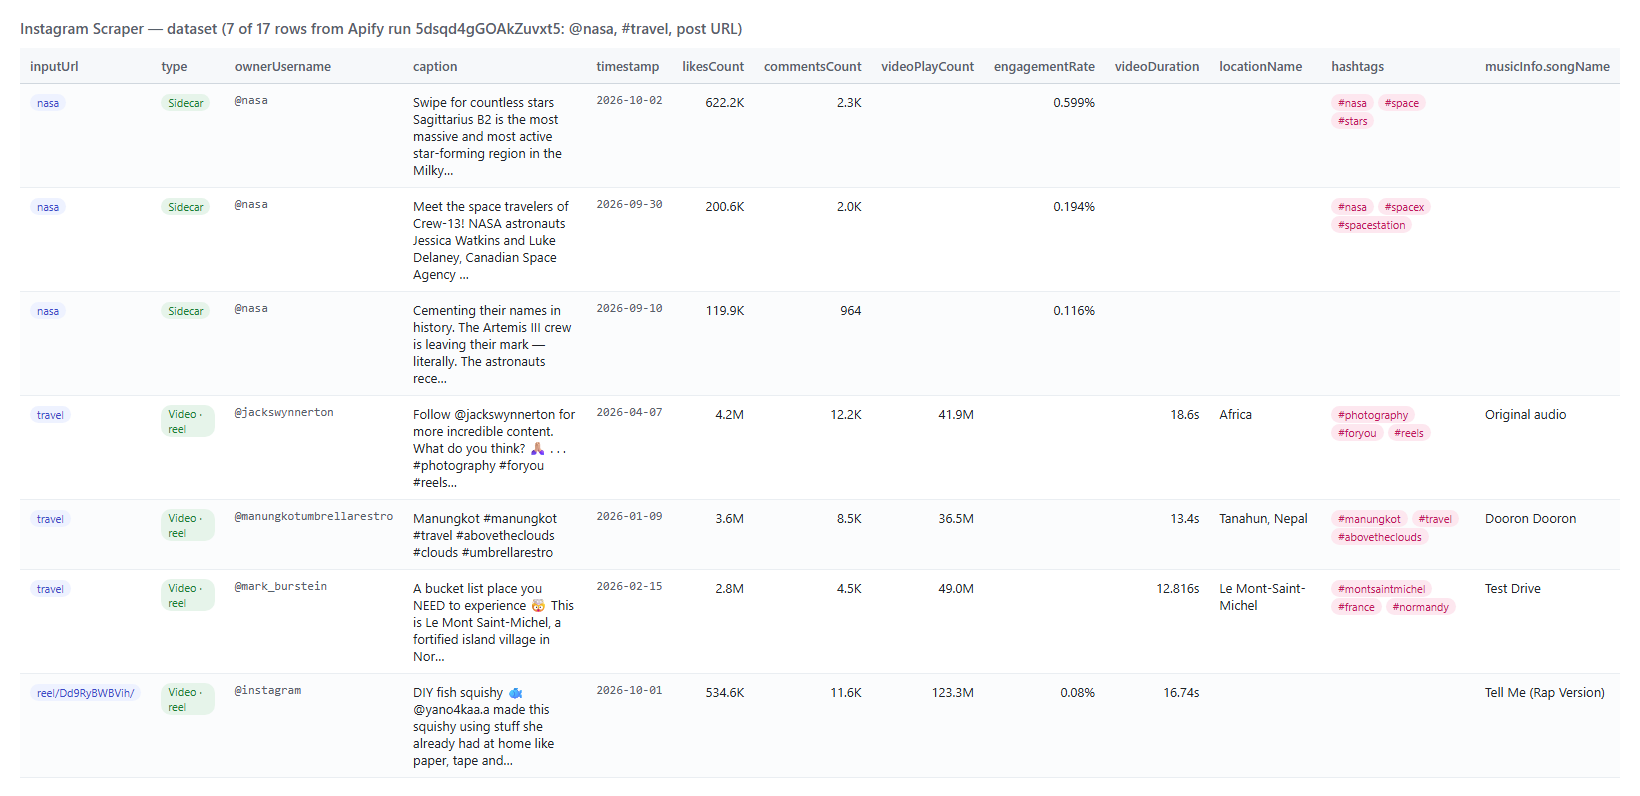
<a href="https://console.apify.com/actors/5UGcwS9WCCJbVqzDY"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/instagram-scraper-output.png" alt="Instagram Scraper output table of Instagram posts with likes, comments, plays and engagement" style="width:70%"></a>

One reel from the 2026-10-20 Reels-tab run, as JSON (long text and media links shortened):

```json
{
  "id": "4011412284387978903",
  "type": "Video",
  "shortCode": "DerZjgilW6X",
  "url": "https://www.instagram.com/reel/DerZjgilW6X/",
  "caption": "From Oscar®-winning filmmakers Elizabeth Chai Vasarhelyi (@chaivasarhelyi) and @jimmychin, discover an intimate portr...",
  "mentions": ["chaivasarhelyi", "jimmychin"],
  "timestamp": "2026-10-19T16:00:04.000Z",
  "likesCount": 27608,
  "commentsCount": 101,
  "engagementCount": 27709,
  "engagementRate": 0.01,
  "videoPlayCount": 1119792,
  "videoViewCount": 189070,
  "playsPerFollower": 0.0042,
  "videoDuration": 60.011,
  "videoUrl": "https://scontent-hou1-1.cdninstagram.com/...",
  "audioUrl": "https://scontent-hou1-1.cdninstagram.com/...",
  "productType": "clips",
  "isPinned": false,
  "paidPartnership": false,
  "taggedUsers": [{ "id": "4721025", "username": "jimmychin", "fullName": "Jimmy Chin", "position": [0, 0] }],
  "musicInfo": { "audioType": "original_sounds", "songName": "Original audio", "artistName": "natgeo", "audioId": "28274177888930642", "usesOriginalAudio": true, "isTrendingInClips": false, "originalAudioOwner": "natgeo" },
  "ownerUsername": "natgeo",
  "ownerFollowersCount": 268324349
}
```

A `changes` monitor row (basic data) adds what moved since the last delivery:

```json
{
  "shortCode": "Deu3BoCBbDP",
  "videoPlayCount": 844221,
  "playCountDelta": 6712,
  "likesCount": 19598,
  "likesDelta": 91,
  "commentsCount": 239,
  "commentsDelta": 2,
  "previousScrapedAt": "2026-10-21T00:49:33.000Z",
  "dataDetailLevel": "basicData"
}
```

#### Fields

Fill is measured on live runs: **Reels** = 100 detailed reels from 4 profiles; **Posts** = a 12-post timeline (6 images, 3 carousels, 3 reels).

| Field | What it is | Reels | Posts |
|---|---|---|---|
| `id`, `pk`, `shortCode`, `url`, `type`, `productType` | Media id, shortcode, URL (`/reel/` for reels); `Image` / `Video` / `Sidecar`; `feed` / `clips` / `carousel_container` | 100% | 100% |
| `caption`, `hashtags`, `mentions` | Caption with hashtags and @mentions parsed | 100% / 69% / 77% | 100% / 58% / 58% |
| `timestamp`, `captionCreatedAt` | Publish time and caption time (ISO 8601) | 100% | 100% |
| `likesCount`, `commentsCount`, `engagementCount` | Likes (null when hidden), comments, their sum | 100% | 100% |
| `engagementRate`, `playsPerFollower` | (likes + comments) / followers, percent; plays / followers (the profile's own posts; collab posts belong to the co-author) | 75% | 75% / 17% |
| `videoPlayCount` (= `igPlayCount`), `videoViewCount` | Reel plays; video views, Instagram's separate counter (median 30% of plays here) | 100% | 25% (every video) |
| `videoUrl`, `audioUrl`, `videoDuration`, `hasAudio` | Video and audio-only (m4a) links, seconds, audio flag | 100% / 98% / 100% / 98% | 25% |
| `musicInfo` | `audioType`, `songName`, `artistName`, `audioId`, `usesOriginalAudio`, `isExplicit`, `isTrendingInClips`, `shouldMuteAudio`, `originalAudioOwner` | 98% | 25% |
| `displayUrl`, `images`, `dimensionsWidth`, `dimensionsHeight` (= `originalWidth`, `originalHeight`) | Largest image and every rendition (signed links, they expire) | 100% | 100% |
| `isPinned`, `isInProfileGrid`, `paidPartnership`, `sponsors` | Pinned, shown in grid, paid partnership and its sponsors | 100% (sponsors 2%) | 100% (sponsors 0%) |
| `taggedUsers`, `coauthorProducers` | Tagged accounts with positions; collaborators | 71% / 42% | 42% / 42% |
| `locationName`, `locationId`, `locationCity`, `locationLat`, `locationLng` | Tagged place | 18% | 0% |
| `childPosts` | Carousel items with their own media and tags | - | 25% (every carousel) |
| `latestComments`, `firstComment` | Newest comments with author, verified flag, time, likes, replies (`includeLatestComments`) | 100% / 88% (26 reels) | - |
| `playCountDelta`, `likesDelta`, `commentsDelta`, `previousScrapedAt` | Change since the last delivery (`monitorDelivery: "changes"`) | 100% (11 reels) | - |
| `ownerUsername`, `ownerFullName`, `ownerId`, `ownerIsVerified`, `ownerProfilePicUrl`, `ownerFollowersCount` | The account that posted | 100% (followers 75%) | 100% (followers 75%) |
| `inputUrl`, `searchTerm`, `searchSource`, `scrapedAt`, `dataDetailLevel` | Where the row came from (`profile`, `reels`, `hashtag`, `url`); `basicData` on rows from the Reels tab or keyword page alone | 100% | 100% |

**Basic rows** (1,000 reels): ids, URL, plays, likes, comments, cover and owner id 100%; owner username, followers, `engagementRate`, `playsPerFollower` 88% (the profile's own reels).

A `Profile` row (add-on) carries `username`, `fullName`, `biography`, `externalUrl`, `bioLinks[]`, `followersCount`, `followsCount`, `postsCount`, `isPrivate`, `isVerified`, `isBusinessAccount`, `isProfessionalAccount`, `businessCategoryName`, `businessAddress`, `profilePicUrl`, `profilePicUrlHD`, `hasActiveStory`, `highlightReelCount`, `hasClips`, `threadsBadge`, `fbid`.

### How can I use Instagram posts and reels data?

- 🎯 **Influencer and creator vetting** - pull a creator's last 100 reels, read `videoPlayCount`, `playsPerFollower`, `engagementRate`, `paidPartnership` and `coauthorProducers` to see real reach and how often they run sponsored content.
- 📈 **Reel performance tracking** - schedule a profile hourly with `monitorDelivery: "changes"` and `basicData`; each run returns the reels that moved with their play, like and comment deltas.
- 📊 **Competitor and brand monitoring** - schedule the competitor profiles daily with `monitorMode` and get every new post, its format and its first-day likes and comments.
- 🔎 **Trend and sound research** - read the keyword page for `travel` or `street food`, rank reels by `videoPlayCount`, pick the sounds in `musicInfo` that trend.
- 📍 **Local marketing and venue research** - `withLocationOnly` keeps posts tagged with a place; group them by `locationName` and `locationCity`.
- 🤖 **AI and research teams** - feed `caption`, `hashtags`, `alt`, `latestComments` and the counts to an LLM with `compact: true`.

### How much does it cost to scrape Instagram?

Instagram Scraper is pay-per-result: **$0.40 per 1,000 posts or reels**, no start fee. One result is one post or reel written to the dataset; views, latest comments and change deltas are included. The optional profile row is $0.001 per profile.

| Rows | Cost |
|---:|---:|
| 10 | $0.004 |
| 100 | $0.04 |
| 1,000 | $0.40 |
| 10,000 | $4.00 |

There is nothing else to pay: Apify platform usage (compute, proxy) is included in these prices. Runs measured on 2026-10-20 (256 MB, no browser): 12 posts from a profile in 7-30 seconds depending on the proxy exit; 100 detailed reels from 4 profiles with views in 80-250 seconds depending on the proxy exit; 1,000 basic reels from one profile in 84 seconds; a monitor run with nothing new delivers nothing and costs nothing.

### Integrations, API, scheduling & MCP

- **Schedules:** run Instagram Scraper hourly, daily or weekly from the **Schedules** tab; combine with `monitorMode` or `onlyPostsNewerThan` to get only new or changed posts.
- **Webhooks:** fire a URL when a run finishes - push rows to your CRM, Slack or a sheet.
- **No-code:** Make, Zapier, n8n, Google Sheets, Airtable, Slack via [Apify integrations](https://docs.apify.com/integrations).
- **API:** call it from Node.js or Python with `apify-client` - code on the [API tab](https://apify.com/topapi/instagram-scraper/api/python) and the [Apify API reference](https://docs.apify.com/api/v2).
- **MCP / AI agents:** connect Claude, Cursor or any MCP client through the [MCP tab](https://apify.com/topapi/instagram-scraper/api/mcp) and ask for Instagram posts in plain language.

### More TopApi scrapers

<table>
<tr>
<td>🎵 <a href="https://apify.com/topapi/tiktok-scraper">TikTok Scraper</a> - videos by profile, hashtag or URL with stats, sound and transcript</td>
<td>⭐ <a href="https://apify.com/topapi/google-maps-reviews-scraper">Google Maps Reviews Scraper</a> - every review of a place with owner replies and dates</td>
<td>🧭 <a href="https://apify.com/topapi">All TopApi actors</a> - social media, reviews and lead-gen scrapers built for scheduled runs</td>
</tr>
</table>

### Limits & empty runs

- **Per page:** 10 timeline posts, 12 Reels-tab or keyword-page reels; `resultsLimit` and the date window are the cost controls.
- **Speed:** each `videoViewCount` is one ~210 KB page (about 3 s, 8 in parallel); switch it off or use `basicData` for the fastest runs.
- **Not available signed-out:** share counts, reels by sound, `postsCount`, followers of accounts seen only on a keyword page. Keyword pages exist for some terms only.
- **Basic rows** have no caption, date, media links or sound; their date window uses the upload time in the reel id.
- **Media links expire** within hours. **Private accounts** give no posts.
- **Empty dataset:** private or unknown profiles, a keyword without a public page, or filters removed everything; the run status names which. Nothing is charged for any of these.

### FAQ

#### How many Instagram posts can Instagram Scraper collect in one run?

As many as the cap allows: 10 per timeline page, 12 per Reels-tab or keyword page, one request per post URL. A run reads pages until `resultsLimit`, `maxItems`, the date window or the end of the profile is reached. The default 50 per profile is 5 pages; set `0` to read a whole profile.

#### Can I scrape Instagram reels with Instagram Scraper?

Yes. Set **Content** (`postType`) to `reel`: profiles are read from their Reels tab with plays, likes and comments on every reel, keyword pages and `/reel/` URLs keep reels only. `basicData` returns counts only, fastest; `detailedData` adds caption, date, video and audio links, sound, tags and location.

#### How do I track reel views over time?

Schedule the profiles with `monitorMode: true` and `monitorDelivery: "changes"`. Each run delivers the reels whose plays, likes or comments changed since the last delivery, with the deltas, so a dataset of runs is a time series of each reel.

#### Can I run Instagram Scraper on a schedule to get new Instagram posts automatically?

Yes. Save your input as a task, open **Schedules**, pick the cadence and turn on `monitorMode`: each run remembers the posts it delivered per profile or keyword. On a profile it stops at the last run's newest post; on a keyword page it walks past the posts it already delivered and returns the next ones up to your cap. A run with nothing new delivers nothing.

#### Does it return share counts?

No. Instagram shows share counts only to signed-in users, and this actor never logs in. Plays, views, likes and comments are all there.

#### Can I use Instagram Scraper with the API, other apps or an MCP server?

Yes. Use `apify-client` for [Node.js](https://apify.com/topapi/instagram-scraper/api/javascript) or [Python](https://apify.com/topapi/instagram-scraper/api/python), connect Make, Zapier, n8n or Google Sheets via [Apify integrations](https://docs.apify.com/integrations), or connect Claude, Cursor or any MCP client through the [MCP tab](https://apify.com/topapi/instagram-scraper/api/mcp) and turn on `compact`.

#### Do I need an Instagram account, cookies or an API key?

No. Instagram Scraper reads only what Instagram shows publicly to a signed-out visitor; you pass usernames, hashtags or URLs and nothing else.

#### Why did my Instagram Scraper run return no results?

In order of frequency seen in testing: the keyword has no public page (try a broader term), the account is private or misspelled, or the date window and filters removed every post. The run status message names the cause.

#### How is Instagram Scraper different from other Instagram scrapers?

It runs without a browser on 256 MB; it reads a profile's whole Reels tab with plays on every row, ships views and plays side by side, `playsPerFollower`, `engagementRate`, trending-sound flags, the audio-only link and every image rendition; it tracks reel growth with change deltas; and it filters by date window, content type, likes, plays, keyword, place and pinned posts.

#### Is it legal to scrape Instagram data?

Instagram Scraper extracts only publicly available Instagram posts; it does not log in or collect private data. Results may still contain personal data, which is regulated (for example by GDPR). Make sure you have a legitimate purpose before you use it.

#### Your feedback

We keep improving Instagram Scraper. Found a bug or missing a field? Open an issue on the [Issues tab](https://apify.com/topapi/instagram-scraper/issues/open) - we answer within one business day.

# Actor input Schema

## `usernames` (type: `array`):

Instagram usernames or profile URLs, e.g. "nasa", "@natgeo", "https://www.instagram.com/instagram/". Newest posts first (pinned first). With Content = Reels, every reel from the profile's Reels tab.

## `hashtags` (type: `array`):

Hashtags, keywords or tag URLs, e.g. "travel", "#foodie", "instagram.com/explore/tags/travel/". Read from Instagram's signed-out keyword page (mostly reels, 12 per page); rows carry searchTerm.

## `postUrls` (type: `array`):

Post / reel URLs or bare shortcodes, e.g. "https://www.instagram.com/p/Dd9RyBWBVih/", "https://www.instagram.com/reel/Dd9RyBWBVih/", "Dd9RyBWBVih". One row per URL.

## `postType` (type: `string`):

Reels reads a profile's Reels tab (also reels not shown in the grid) with plays, likes and comments on every row; on hashtags and URLs it keeps reels only. Carousels come back as type "Sidecar".

## `dataDetailLevel` (type: `string`):

For reels from a profile's Reels tab and for hashtags. Basic skips the per-reel detail request: no caption, date or media URLs, about 30x less data. Profile timelines always come detailed.

## `onlyPostsNewerThan` (type: `string`):

Absolute date (2026-09-01, 2026-09-01T12:00:00Z), relative (7 days, 3 weeks, 2 months) or a day count (1 = today's posts). Empty = no lower bound. Pinned posts are judged by their own date.

## `onlyPostsOlderThan` (type: `string`):

Absolute date or relative (e.g. 30 days). Combine with the field above for a window such as "2026-01-01" to "2026-06-30".

## `skipPinnedPosts` (type: `boolean`):

Leave out the posts and reels a profile pinned to the top of its grid or Reels tab (often old). They are counted in the run summary.

## `minLikes` (type: `integer`):

Keep only posts with at least this many likes, e.g. 10000 for hits only. 0 = no minimum. Posts whose owner hides like counts have likesCount null and are kept.

## `minPlays` (type: `integer`):

Keep only reels with at least this many plays, e.g. 100000 for viral reels. 0 = no minimum. Rows without a play count (photos, carousels) are dropped when this is set.

## `keywordFilter` (type: `string`):

Keep only posts whose caption, hashtags, tagged users, location, owner or song contain this word, case-insensitive, e.g. "giveaway" or "recipe, meal prep" (comma = any). Needs detailed data.

## `withLocationOnly` (type: `boolean`):

Keep only posts that carry a location tag (locationName, locationId, city). Useful for local lead lists and venue research. On a 30-post test sample 7% of posts had one.

## `includeVideoViewCount` (type: `boolean`):

Adds videoViewCount to every video and reel row: Instagram's view counter, separate from plays (views were a median 30% of plays on 100 test reels). Free. Skipped in Basic reel detail.

## `includeLatestComments` (type: `boolean`):

Adds latestComments (the newest 12-15 comments with author, time and likes) and firstComment to every row that has comments. Free; one extra request per row. Skipped in Basic reel detail.

## `includeProfileSummary` (type: `boolean`):

Adds one row of type "Profile" per scraped profile: followers, following, bio, links, verified / private / business flags, category, business address, HD avatar. Charged as profile-summary.

## `monitorMode` (type: `boolean`):

Remembers per profile / hashtag which posts were delivered (in the key-value store below). On a profile the run stops at the last run's newest post, so a daily check costs one page.

## `monitorDelivery` (type: `string`):

Changes re-reads the newest posts / reels of each profile (up to your per-target cap) and delivers those whose counts moved, with playCountDelta, likesDelta, commentsDelta. Profiles and URLs.

## `monitorStoreName` (type: `string`):

Key-value store that keeps the monitor memory. Give each separate feed (a client, a Slack channel) its own name so they do not hide posts from each other. Letters, digits, hyphens.

## `resultsLimit` (type: `integer`):

Cap per target after filters (your main cost control; you pay per delivered post). 0 = everything Instagram serves (10 posts per timeline page, 12 per reels or keyword page).

## `maxItems` (type: `integer`):

Hard cap for the whole run across all targets. 0 = no total cap (each target is still capped above).

## `compact` (type: `boolean`):

Core fields only (id, type, shortCode, url, caption, hashtags, timestamp, likes, comments, engagement, plays, views, media URL, duration, pinned, location, music, owner): sized for AI agents and MCP.

## `proxyConfiguration` (type: `object`):

Apify datacenter proxies serve every request this actor makes (measured on profiles, reels tabs, keyword pages and single posts). A fresh proxy session is used when Instagram asks a session to wait.

## `maxConcurrency` (type: `integer`):

How many per-post requests run at once (reel and keyword details, view counts, comments, post URLs). 4 is a safe default; raise to 8 for big URL lists.

## Actor input object example

```json
{
  "usernames": [
    "nasa"
  ],
  "hashtags": [],
  "postUrls": [],
  "postType": "all",
  "dataDetailLevel": "detailedData",
  "skipPinnedPosts": false,
  "minLikes": 0,
  "minPlays": 0,
  "keywordFilter": "",
  "withLocationOnly": false,
  "includeVideoViewCount": true,
  "includeLatestComments": false,
  "includeProfileSummary": false,
  "monitorMode": false,
  "monitorDelivery": "new",
  "monitorStoreName": "instagram-posts-monitor",
  "resultsLimit": 12,
  "maxItems": 0,
  "compact": false,
  "proxyConfiguration": {
    "useApifyProxy": true
  },
  "maxConcurrency": 4
}
```

# Actor output Schema

## `posts` (type: `string`):

The dataset of Instagram posts (one item per post, reel or carousel; profile summary rows have type Profile).

## `summary` (type: `string`):

Per-target counts (read, filtered, already delivered, delivered), requests made, sessions used and bytes transferred. Written for runs started in the Console, runs of 25 or more posts and runs where a target failed; the same counts are in every run's log.

# API

You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.

## JavaScript example

```javascript
import { ApifyClient } from 'apify-client';

// Initialize the ApifyClient with your Apify API token
// Replace the '<YOUR_API_TOKEN>' with your token
const client = new ApifyClient({
    token: '<YOUR_API_TOKEN>',
});

// Prepare Actor input
const input = {
    "usernames": [
        "nasa"
    ],
    "resultsLimit": 12
};

// Run the Actor and wait for it to finish
const run = await client.actor("topapi/instagram-scraper").call(input);

// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
    console.dir(item);
});

// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs

```

## Python example

```python
from apify_client import ApifyClient

# Initialize the ApifyClient with your Apify API token
# Replace '<YOUR_API_TOKEN>' with your token.
client = ApifyClient("<YOUR_API_TOKEN>")

# Prepare the Actor input
run_input = {
    "usernames": ["nasa"],
    "resultsLimit": 12,
}

# Run the Actor and wait for it to finish
run = client.actor("topapi/instagram-scraper").call(run_input=run_input)

# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
    print(item)

# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start

```

## CLI example

```bash
echo '{
  "usernames": [
    "nasa"
  ],
  "resultsLimit": 12
}' |
apify call topapi/instagram-scraper --silent --output-dataset

```

## MCP server setup

```json
{
    "mcpServers": {
        "apify": {
            "type": "http",
            "url": "https://mcp.apify.com/?tools=fetch-actor-details,topapi/instagram-scraper"
        }
    }
}
```

The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer <APIFY_API_TOKEN>` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).

## OpenAPI specification

Download the OpenAPI definition: https://api.apify.com/v2/actors/5UGcwS9WCCJbVqzDY/builds/CGHsjYbylp1tBWaGb/openapi.json
