Read Replicas Make Your Database Faster to Ask, Not Faster to Be Right


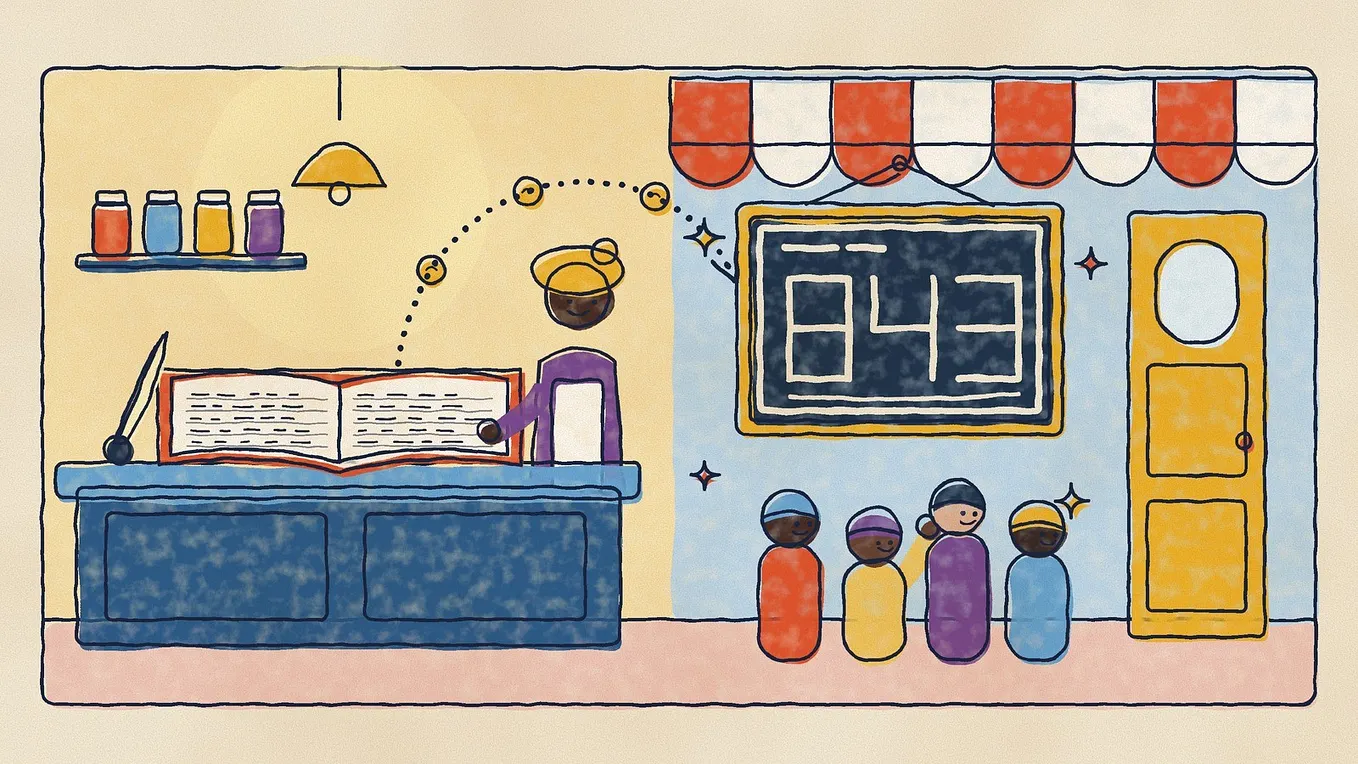
Imagine a company with one head office and ten branch shops. The head office keeps the official price list. Every branch holds a copy, delivered by courier. Customers walk into the branches, so the head office is never swamped, and everyone is happy.
Then, at 9:00, a price changes. The head office updates the list at once. The courier is still on the road. For the next few minutes, one branch quotes the old price to anyone who asks. Nothing is broken. The system is doing exactly what it was built to do. It is just not instant.
That is a read replica. It is a second database that receives every change from the main one, the primary, and answers read-only questions. Your reads spread across many machines, and the primary gets room to breathe. The price is that a replica is always a little behind, and sometimes a lot behind.
In a previous post here, we made copies of data inside one database, and saw that every copy needs someone to keep it fresh. A replica is the same idea at the level of a whole database, and the same bill arrives.
What the manuals admit about lag
PostgreSQL’s manual says it directly: the data on the standby takes some time to arrive from the primary, so there will be a measurable delay between primary and standby [S1]. Its standby is strictly read-only, and not even temporary tables may be written there [S1].
PostgreSQL gives you three clocks for measuring this. On the primary, the view pg_stat_replication shows write_lag, flush_lag and replay_lag for each standby [S2]. They measure the time between flushing recent WAL on the primary (WAL is the database’s diary of changes) and being told the standby has written it, flushed it, or fully applied it [S2]. Only replay_lag tells you when a reader on the standby could actually see the change [S2]. Two cautions from the same page: these are not predictions of how long catching up will take, and on a fully caught up, idle system the columns return to NULL after a short time, so your monitoring must decide whether NULL means zero or missing [S2]:
SELECT application_name, sync_state, write_lag, flush_lag, replay_lag
FROM pg_stat_replication;
Microsoft says the same thing about SQL Server’s readable secondary replicas: there is latency, usually only a matter of seconds, but in unusual cases, such as network issues reducing throughput, it can become significant, and it rises when I/O bottlenecks occur or data movement is suspended [S5]. The guidance is blunt: use secondaries if your read workloads can tolerate some latency, and where latency is unacceptable, run them against the primary [S5].
Oracle can open a standby for queries while it keeps applying changes, a feature called real-time query, and it requires the Oracle Active Data Guard option licence [S8]. Apply lag is defined as the time between when a change became visible on the standby and when it was first visible on the primary, and you can watch it in V$DATAGUARD_STATS [S8].
MongoDB is the most direct of all. Its manual says all read preference modes except primary may return stale data, because secondaries replicate from the primary asynchronously, and you should make sure your application can tolerate that [S10]. Also, the default mode is primary, so replica reads in MongoDB are something you opt into [S10].
The nastiest effect of lag is not a stale dashboard. It is a user who changes something and is immediately shown the old value. A customer saves a new address, the next page loads from a replica that has not caught up, and the old address stares back. They save again. They contact support.
There are three honest ways out:
First, send that user’s reads to the primary for a short window after they write. It is simple and works on every database. In a previous post here, we looked at connection pools, and a separate pool for the primary and for the replicas is a natural place to make this choice.
Second, make the write wait. PostgreSQL’s synchronous_commit setting accepts remote_apply, which makes a commit wait until the standby has replayed it, so queries on that standby can see it [S3]. The manual warns this causes much larger commit delays than the other settings, because it waits for replay [S3]. It only has an effect when synchronous standbys are configured [S3].
Third, use the database’s own consistency tools. MongoDB’s manual notes that causal consistency guarantees with majority read and write concern hold across all members, and that read preference does not change that [S10]. Reads inside a transaction must use the primary [S10].
Set a limit on staleness
Most of the time you do not need a replica to be perfect. You need it not to be badly behind. Each database lets you say so.
In Oracle, a session can set a tolerance. A nonzero value STANDBY_MAX_DATA_DELAY lets queries run only if apply lag is at or below it, and otherwise returns error ORA-3172 [S8]. Setting it to 0 asks for exactly the primary’s answer, and it also needs synchronous transport, real-time apply, and a synchronized status [S8]. Your code catches ORA-3172 and retries on the primary:
ALTER SESSION SET STANDBY_MAX_DATA_DELAY = 2;
In MongoDB, maxStalenessSeconds tells the driver to stop using any secondary whose estimated lag is above the value [S11]. The minimum is 90 seconds, because the estimate is coarse and based on periodic checks, and by default there is no maximum at all [S11]:
mongodb://host1,host2,host3/?replicaSet=rs0&readPreference=secondaryPreferred&maxStalenessSeconds=120
In SQL Server, an application opts in by declaring a read-intent connection, and read-only routing through the availability group listener sends it to a readable secondary [S5]. Microsoft notes that read-intent requests can be load balanced across replicas, and that all queries on a secondary are mapped to snapshot isolation with locking hints ignored [S5]:
Server=ag-listener;Database=shop;ApplicationIntent=ReadOnly;
Get Rufus Kehinde’s stories in your inbox
Join Medium for free to get updates from this writer.
In PostgreSQL, the manual does not give a built-in per-query lag limit on the page I used. The usual answer is to watch replay_lag and route traffic away from a replica that falls behind your limit [S2].
How a replica can hurt the primary
This is the part that surprises people, because the replica is supposed to be the safe place to run heavy queries.
In PostgreSQL, the primary does not know what queries run on a standby, so it will not wait for them [S1]. When a standby query conflicts with incoming changes and the delay limit passes, the query is cancelled, which usually shows up as just a cancellation error [S1]. The fix many teams reach for is hot_standby_feedback, which stops VACUUM from removing recently dead rows so cleanup conflicts do not occur, but it delays cleanup on the primary and may cause undesirable table bloat [S1].
SQL Server has two versions of this. Because secondary reads use row versioning, the primary adds 14 bytes of overhead to changed rows when read access is enabled, which can cause page splits, and tempdb on the secondary needs space [S5]. And read workloads on a secondary can block DDL changes being applied through the log, and the cleanup of ghost records on the primary can be blocked by transactions on a secondary, which also prevents log truncation [S5].
The tradeoff
A read replica gives you more read capacity, a place to run reports away from the primary, and in most setups a warm copy for failover. It costs you in these ways:
- Answers are sometimes old, so every read needs an opinion about how old is acceptable.
- A user’s own writes may not be visible right away, so you need a routing rule.
- Waiting for the replica on every commit makes writes slower, and not waiting means you accept lag [S3].
A replica adds work for the primary and for your team. The primary may hold more history, as PostgreSQL’s feedback setting shows [S1], and someone has to watch the lag, the disk, and the connection to each replica.
A replica multiplies reads, not writes. Every replica applies the same stream of writes as the primary, so a write-heavy system does not get faster by adding more of them. That last point is engineering judgment, not a quote from a manual.
My rule is to try the cheapest fixes first: an index from a previous post here, a query plan check from a previous post here, and a cache from a previous post here. Add a replica when reads are the real bottleneck and some of them can honestly be a few seconds old.
The security angle
A replica is not a lesser copy. It holds the same data as the primary, so anything that protects the primary has to protect it too. Here is what I check.
Treat the replica as production data. PostgreSQL’s manual stresses that only trusted users should be able to read the WAL stream, because it is easy to extract privileged information from it [S4]. The same logic covers the replica itself: encryption at rest, network rules, audit logging, and patching should match the primary. That is judgment, but it follows from the fact that the replica holds the same rows.
Give the replication link its own account, with only that right. PostgreSQL’s manual says the standby must authenticate as an account with the REPLICATION privilege, recommends a dedicated account with REPLICATION and LOGIN, and notes that this privilege does not let the user modify data on the primary [S4]. Access is controlled by a pg_hba.conf record that uses the special word replication in the database field, and the manual’s example limits it to one address with scram-sha-256 [S4]:
host replication foo 192.168.1.100/32 scram-sha-256
Authenticate and encrypt the link between nodes. Each database has its own way:
SQL Server configures authentication and encryption on the database mirroring endpoint used by availability groups [S6]. Windows Authentication is recommended when every instance runs under a domain account, and certificates are required when a built-in or non-domain account is used [S6]. An older Microsoft page, for SQL Server 2012, says encryption is required by default, recommends requiring it unless you can guarantee the network is secure, and recommends AES over RC4, which it calls deprecated [S7]. That page is old, so check the current default on your version.
Oracle sends redo over Oracle Net sessions [S9]. SSL can be used for redo transport authentication when a set of conditions is met, including Oracle Internet Directory, wallets, and certificates. Otherwise, each database uses a remote login password file, and the password of the authenticating user, SYS by default, must match at both ends [S9]. That page does not state that redo is encrypted in transit, so confirm network encryption separately.
MongoDB members can authenticate each other with keyfiles or X.509 certificates, and enabling internal authentication also enables client authorization [S12]. A keyfile must be 6 to 1024 characters of base64 [S12].
For PostgreSQL, the streaming replication page I read does not mention encrypting the connection, and its sample connection string even contains a plaintext password [S4]. Look up the TLS options for replication connections in the PostgreSQL documentation for your version before you decide.
Never let a lagging replica make an authorization decision. If you revoke a user’s access, disable an account, or invalidate a session, the change reaches the replica a little later. For that window, a replica can still show the user as active. So permission checks, token and session revocation, balances, stock counts, and anything where being wrong has a security or money cost should read from the primary. SQL Server’s guidance to use the primary where latency is unacceptable [S5] and MongoDB’s rule that transactions read from the primary [S10] point the same way. The specific revocation example is my judgment, derived from the documented lag.
Remember who reads from the replica. Reporting tools and analysts often get replica access because it feels safe. It is read-only, but reading is exactly how data leaks. Give those accounts the least access they need, and do not hand out the replica’s admin rights.
Deletion is not finished until the replicas agree. If you delete a customer’s record on the primary, a lagging replica still holds it for a while, and so do your backups. For privacy and retention commitments, make sure your process counts replicas and backups, not only the primary. This is judgment, not a quote.
A stuck replica can take the primary down. PostgreSQL replication slots keep WAL until every standby has received it, and the manual warns they can retain so many segments that they fill the space allocated for pg_wal, with max_slot_wal_keep_size as the limiting setting [S4]. A forgotten or broken replica is therefore an availability risk, not just a monitoring gap.
Three questions before you add one
1. Which reads can honestly be a few seconds old, and which cannot?
2. What does a user see right after their own write?
3. Who watches the lag, and what do we do when it passes our limit?
Write the answers down, and give every read a freshness label before you choose where it runs.
Sources
S1: PostgreSQL manual, Hot Standby. https://postgresql.org/docs/current/hot-standby.html
S2: PostgreSQL 17 manual, Cumulative Statistics System (pg_stat_replication). https://www.postgresql.org/docs/17/monitoring-stats.html
S3: PostgreSQL manual, Write Ahead Log settings (synchronous_commit). https://postgresql.org/docs/current/runtime-config-wal.html
S4: PostgreSQL manual, Log-Shipping Standby Servers (streaming replication). https://postgresql.org/docs/current/warm-standby.html
S5: Microsoft Learn, Readable secondary replicas in Always On availability groups. https://learn.microsoft.com/sql/database-engine/availability-groups/windows/active-secondaries-readable-secondary-replicas-always-on-availability-groups
S6: Microsoft Learn, The database mirroring endpoint. https://learn.microsoft.com/en-us/sql/database-engine/database-mirroring/the-database-mirroring-endpoint-sql-server?view=sql-server-2017
S7: Microsoft Learn (SQL Server 2012 archive), Transport Security for Database Mirroring and AlwaysOn Availability Groups. https://learn.microsoft.com/en-us/previous-versions/sql/sql-server-2012/ms186360(v=sql.110)
S8: Oracle Database 19c Data Guard Concepts and Administration, Managing Physical and Snapshot Standby Databases. https://docs.oracle.com/en/database/oracle/oracle-database/19/sbydb/managing-oracle-data-guard-physical-standby-databases.html
S9: Oracle Database 21c Data Guard Concepts and Administration, Redo Transport Services. https://docs.oracle.com/en/database/oracle/oracle-database/21/sbydb/oracle-data-guard-redo-transport-services.html
S10: MongoDB manual, Read Preference. https://www.mongodb.com/docs/manual/core/read-preference/
S11: MongoDB manual, Read Preference maxStalenessSeconds. https://www.mongodb.com/docs/manual/core/read-preference-staleness/
S12: MongoDB manual, Internal/Membership Authentication. https://www.mongodb.com/docs/manual/core/security-internal-authentication/