Kafka Retry Strategy — Choosing How and When to Retry


Introduction
In the first article, we established the principles of retry design. We defined failure categories and criteria for classifying failures, and concluded that configuration should be the result of the retry strategy and not the driver.
In this article, we will focus on retry timing and what should or shouldn’t happen during the retry period. We will examine how the choice between blocking and non-blocking retry affects the processing flow, what backoff is and how its parameters need to be determined.
Blocking vs Non-Blocking
Design principles
The main question the design should address is whether to suspend processing of subsequent messages in the flow. In Kafka, the message ordering is guaranteed within individual partitions rather than across the entire topic, so partition boundaries play a significant role in the retry design. Each partition is assigned to a single consumer within a consumer group; consequently, blocking the processing of a message delays subsequent messages in the affected partition. Depending on business and operational requirements, we may consider the following:
- Is out-of-order execution acceptable?
- Is it acceptable for one failed message to delay unrelated messages?
- How does the selected solution affect overall throughput?
Blocking Retry
Blocking retry suspends the processing of further messages until the current message has been processed successfully or its failure has been handled according to the exhaustion policy. The blocking effect is primarily associated with the affected partition, but its scope depends on the consumer’s threading model.

Services that must preserve message ordering may benefit from blocking retry, but it comes at a considerable cost in processing delay and potentially throughput. If our service has to provide high throughput, blocking retry may not be the best option.
Non-Blocking Retry
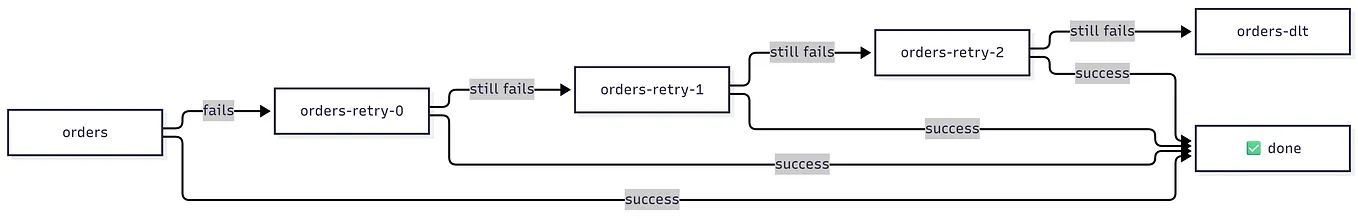
Non-blocking retry reroutes the problematic message to a dedicated path. After the first failed attempt, the message is routed to the retry path and the main flow can continue processing subsequent messages. On the retry path, the message will be reprocessed according to the configured schedule.

However, this approach also comes at a cost: the original processing order can be disrupted after the first message is moved to the retry path, depending on the timing of the retry and the main flow. Even if strict processing order is not a hard requirement, the processing of later messages may depend on state changes conveyed by earlier messages.
Blocking vs Non-Blocking Retry
The two approaches are not necessarily mutually exclusive. Depending on the business and technical requirements, we can combine both approaches in our service. A short sequence of blocking retries combined with a non-blocking retry path can be suitable in many use cases.

Retry timing and backoff
Once we have determined whether blocking, non-blocking or a hybrid solution is the best match for the business and technical requirements, we need to examine the retry timing and backoff options. A good retry design should consider the behaviour of downstream systems, the service’s own SLA, and other requirements as discussed in the first article. Based on the design, we will need to specify the following parameters:
- Retry window: How long are we willing to keep trying automatically?
- Backoff strategy: When within this period should we try again?
- Maximum attempts: How many attempts are reasonable in the retry window?
The retry window, maximum attempts and backoff strategy together form the timing configuration. The relationship between these parameters depends on which business or technical requirements take precedence. The design of the retry configuration is iterative rather than hierarchical, and it consists of the following recurring steps:
- Identify the higher-priority constraints based on the business and technical requirements.
- These constraints determine which parameters take precedence. Start with the highest-priority constraint and narrow the options down to feasible combinations of the retry window, backoff strategy and maximum attempts.
- Select a combination that satisfies all mandatory constraints and best meets the remaining priorities. If no feasible combination exists, revisit the requirements or the processing design.

Retry window
The retry window specifies the maximum duration of the automatic retry process, including the first failure. Depending on the backoff strategy and the maximum number of attempts, a longer retry window may unnecessarily overload the downstream systems with repeated requests from the retry path. On the other hand, a retry window that is too short may cause premature routing of the message to the DLT path. The DLT/DLQ is not a black hole, but the recovery cost and delay are typically higher than those of the automatic retry. The design of the retry window should consider the following:
- What is the typical recovery time of the downstream system?
- What is the cost of replay from the DLQ/DLT path?
- How long does a message remain relevant from a business perspective?
- What is the resource consumption of the retry path if multiple messages are waiting for retry?
Backoff strategies
While the retry window defines the maximum duration of the retry process, the backoff strategy specifies when each attempt occurs within the retry window. The specification of a backoff strategy always involves two elements: the backoff pattern and the exact delay parameters within the retry window. The backoff pattern defines the relationship between retry delays. The design of the backoff strategy should consider the following:
- The downstream system’s typical recovery time and pattern.
- How the probability of recovery changes over time.
- The maximum load the downstream system is able to handle in the retry window.
- The resource cost of a single attempt within our service.

Fixed backoff
Get Csaba Filipinyi’s stories in your inbox
Join Medium for free to get updates from this writer.
Fixed backoff specifies a constant delay between attempts. 5s, 5s, 5s, 5s...
Pros:
- Simple and predictable
Cons: - The retry pressure doesn’t adapt over time
Linear backoff
This approach uses a fixed increment that is added to the previous delay after each attempt: 5s, 10s, 15s, 20s
Pros:
- Gradually reduces retry pressure on an unhealthy dependency while still keeping the attempts relatively frequent
Cons: - If the dependency has a longer recovery time, this can result in many failed attempts
Exponential backoff
The gap between attempts grows exponentially: 5s, 10s, 20s, 40s
Pros:
- Quickly reduces the retry pressure on the dependency
Cons: - Long delays can postpone recovery detection after the dependency becomes healthy again.
Custom backoff
The delay sequence doesn’t have to follow any simple predefined mathematical formula, for example: 5s → 15s → 30s → 2m → 5m
Pros:
- Easy customisation according to predictable dependency recovery patterns
Cons: - Tight coupling to the downstream system’s characteristics can make the retry behaviour inefficient if those characteristics change
Jitter
Jitter is not a backoff strategy as such; it is instead a modifier applied to the above strategies. Jitter introduces a random variation into the actual retry delay. It helps to prevent synchronised retry traffic peaks when a large number of messages are being retried.

Maximum attempts
We also need to specify how many attempts are reasonable. In this article, maximum attempts includes the initial processing attempt: five attempts therefore allow up to four retries. Whether this is the primary constraint or is derived from the other two, we need to consider how it affects the resource consumption of both the downstream system and our own service. When determining the maximum number of attempts, we should consider the following design aspects:
- What is the execution cost of one attempt within our service boundaries?
- What is the execution cost of one attempt in the dependency?
- What is the cumulative cost of multiple attempts under high traffic volume? The execution cost of a single attempt may be acceptable, but we also need to consider the total cost under the maximum expected retry load.
Conclusions
In this article, we reviewed how the retry policy can be developed and how retry configuration parameters need to be defined based on the retry design. The different retry-timing options are also driven by business and technical requirements. These parameters are interdependent, which may require iterative design. Blocking and non-blocking retries have their own trade-offs, but they are not mutually exclusive approaches.