Genetic traveling salesman problem. Part 1 — introduction.
The traveling salesman problem (TSP) is one of the most popular algorithmic problems. It stands for:
Given n cities with route cost function between each. Find the best route (least cost) that visits each city exactly once and returns to the initial city.
In general, the initial city is not given so an algorithm should pick one.
The most common version of TSP that we will discuss is a symmetric TSP i.e. for all cities, the cost of (a,b) equals the cost of (b,a).
In this article series, we will:
- Describe 3 TSP algorithms:
- exact (brute-force) algorithm,
- NN (nearest neighbor) algorithm
- genetic algorithm. - Implement these algorithms using Python.
- Examine algorithms performance and explore genetic algorithm parameters.
- Combine NN and genetic algorithm to get better results.
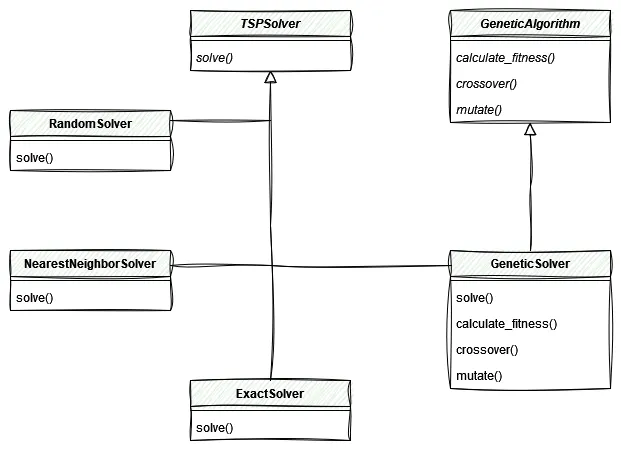
The source code is available on github.
Exact algorithm
The exact algorithm searches the entire solution space, so in order to find the best route it has to make as many comparisons as there are possible solutions. First, we select one of n cities, then we go to one of n-1 cities, and so on. TSP for n cities has n! possible solutions and that’s the exact algorithm computational complexity — O(n!). In other words, the number of possible solutions is equal to the number of permutations of an n-element set.
Example
Let’s say we have 4 cities A, B, C, and D. Routes costs are given in the table below which cells may be interpreted as the cost of traveling from city i (row index) to city j (column index). The table is symmetric because it represents symmetric TSP and naturally diagonal values are not defined.

The calculations have been omitted — there are in total 4!=24 cost function evaluations. However, the cost function value set contains only 2 numbers — 24 and 28. The best path is one of the paths with cost equal to 24 — for example A->B->D->C->A.
Nearest neighbor algorithm
The nearest neighbor algorithm is straightforward to define:
Always go by the locally (from current city) shortest route.
First, we choose one of the n cities, then we compare routes to each of n-1 cities and we pick the best one, then we compare routes to each of n-2 cities, and so on. We repeat this procedure until all cities are visited. The computational complexity of this procedure is equal to O(n²) because a total number of comparisons is given by:
If there is more than one best direct route in the NN algorithm step then we can pick the route :
- randomly,
- which target city index is the least,
- with some optimization — for example, check the next step (if exists) best direct path price.
In the following implementation, if this situation occurs, we will pick a route by its target city index.
Example
With the same data, as in the exact algorithm, we randomly choose city B as an initial city. The shortest route from city B is to city C, then from city C to city D, then from city D, we have to go to city A and then go back to initial city B. Total route cost is:

If we choose another initial city, for example, D, then the best route total cost is cost(D,C,A,B,D)=2+3+10+9=24. We see that the nearest neighbor algorithm result depends on the initial city selection.
Genetic algorithm
Genetic algorithms are generally hard to interpret. It’s not possible to describe in one sentence how the genetic algorithm solves TSP as it was with exact and NN algorithms. We can define a genetic algorithm as:
A genetic algorithm is a way of finding the best solution to a problem modeled on a biological evolution.
Definitions
First, we shall provide some definitions that are required to characterize a genetic TSP solver.

- Population — set of possible problem solutions (set of routes).
- Individual — single population member (single route).
- Genotype — information that unambiguously identifies an individual (order of cities on the route).
- Fenotype — part of the genotype that is subject to evaluation of the fitness function (for TSP identical to genotype).
- Gene — the basic unit of genotype information (a single city on the route, for TSP single gene must be unique in genotype)
- Fitness function — a function that measures the quality of the individual (cost function that calculates the cost of the route).
- Generation — population in successive algorithm iterations.
- Selection — selection of the best-fitted individuals from the generation that will reproduce succeeding generations.
- Crossover — creation of child’s genotype by mixing parent's genes (for TSP we shall ensure that genes are unique).
- Mutation — random changes in the genotype of the new individual.
Algorithm
The genetic TSP algorithm may be described as follows:
- Initialize population.
- Make a selection of individuals.
- Reproduce selected individuals:
a. Crossover
b. Mutation - Create a new generation.
- If STOP then return the best-fitted individual from the current generation. Else back to 2.
The procedure above is described at a high level and doesn’t provide much details. The first step — population initialization — in the beginning will be done totally randomly. Then in the following article, we will try to optimize population initialization with the nearest neighbor algorithm.
Get kuna728’s stories in your inbox
Join Medium for free to get updates from this writer.
Afterward, we will provide 4 selection methods:
- Tournament selection — picking the best individual from n (population size) tournaments. Parametrized by a number of individuals in the tournament.
- Roulette wheel selection — each individual is placed on the circle sector with an angle proportional to its fitness, all individuals create a full circle. Then we spin the roulette wheel (choose a random point on the circle perimeter) and pick a drawn individual. This procedure is repeated until n individuals are drawn.
- Rank selection — same as roulette wheel selection but the circle sector angle is proportional not directly to the individual fitness but to the place of the individual in population ranking.
- Steady-state selection — crossover 2 best-fitted individuals in the current generation. If the resulting offspring is better fitted than the least fitted individual from the current generation then replace them.
The crossover step is already contained in steady state selection so it should be omitted if we have chosen this selection method. For other selection methods, the crossover procedure is as follows:
- Randomly select 2 individuals from the selection.
- Crossover these individuals i.e. create offspring genotype by randomly selecting genes from parents genotypes. For TSP resulting genotype must still contain unique genes.
- Add offspring to the new generation.
- Repeat the steps above until the new generation size is not equal to the population size.
Finally, we will mutate the new generation. This step is important because usually it leads to better algorithm results.
Mutating stands for providing random changes in offspring genotype. In TSP mutation will be implemented as a swapping place of 2 cities on the route. Mutation should be parametrized by the mutation rate.
After the steps above one algorithm iteration (one generation) is done. Now we should check the STOP condition — for example, the desired number of generations. If it’s true then we return the best-fitted individual from the new generation. If not then we set the new generation as a current generation and do another iteration.
Algorithm parametrization is also a crucial problem. Specific parameter values may lead to better results in specific use cases. To summarize, the algorithm can be parametrized by:
- population initialization method,
- population size,
- selection method (and tournament size for tournament selection),
- mutation rate,
- number of generations.
Computational complexity
The computational complexity of the genetic algorithm is not obvious to determine. It depends on:
- genotype length (number of cities) n,
- number of generations g,
- population size p.
It can be defined as:

Where:
- F — computational complexity of fitness function.
- C — computational complexity of crossover function.
- M — computational complexity of mutation function.
In the implementation discussed in the next article, each function has computational complexity not greater than O(n), which implies that their sum is also O(n). Moreover, by default p~n and g=const, so the total algorithm’s computational complexity is equal to O(n²).
Worth noting is the fact that for p=const, the total algorithm’s computational complexity would be linear.
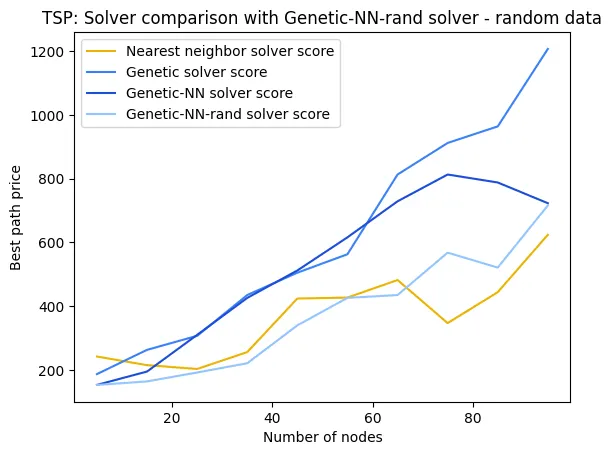
In general population size is a tricky question — an assumption that for linear n it would work fine may be deceptive. We also can’t make it bigger because it would become exponentially complex. In the following articles we will see that this implementation of the genetic algorithm works very well for small n and as it increases so does the genetic algorithm score. It’s due to the fact that in population initialization we randomly pick ~n individuals out of n!. For larger n it’s hard to get well-fitted individuals so it’s also hard for the genetic algorithm to evolve well.
In this article, we’ve described 3 TSP algorithms.
The exact (brute force) algorithm is definitely too expensive to use so we should find a heuristic one.
Then we introduced a really simple NN (nearest neighbor) algorithm — very easy to describe, use, and implement TSP algorithm.
Finally, we characterized the genetic algorithm — a bit complicated algorithm which solves problems that can be modeled as biological evolution. We’ve also seen that TSP can be easily modeled as a biological evolution problem where cities are genes and the order of cities on the route is a genotype.
The genetic algorithms topic has not been exhausted, of course, because it is a vast subject. We provided a general overview required for modeling TSP as a genetic problem and some extras.
In the next article, we will implement the algorithms described in this article.