Member-only story
LLM Observability: What Should Engineers Measure?


Traces, tokens, latency, and quality — a practical framework for building reliable production LLM systems
A fast response can still be wrong. A cheap response can still violate policy. And a successful API request can still represent a failed user task. This is why conventional application monitoring is necessary but insufficient for systems built on large language models.
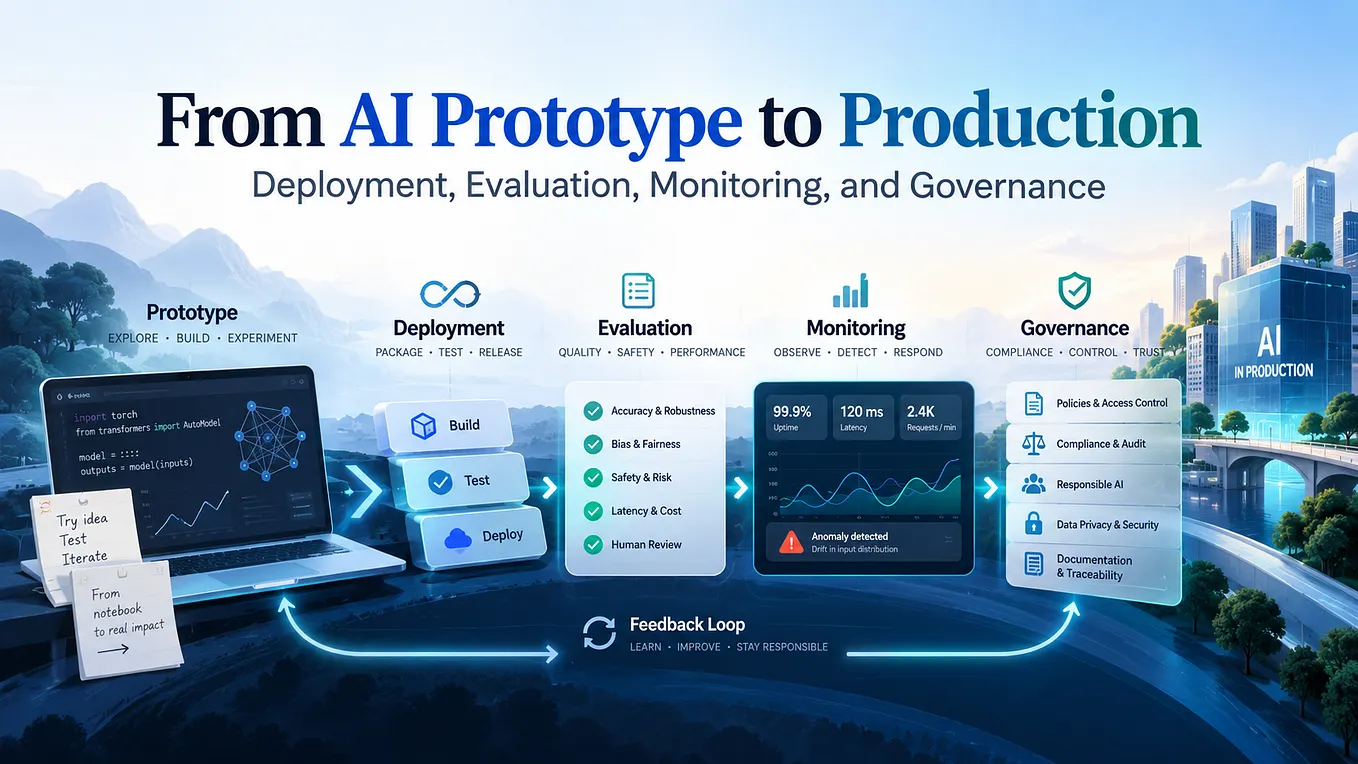
The following is the flow diagram

LLM observability should answer four questions:
What happened?
How much did it cost?
How long did it take?
And did the system actually do the right thing? The challenge is connecting these questions into evidence that engineers, product owners, and engineering leaders can act on.
1. Observability is not the same as logging
Traditional services commonly expose request rates, error rates, CPU utilization, and latency. An LLM application adds variable outputs, prompt context, retrieval, tool execution, safety boundaries, and model-dependent cost. A request can be HTTP 200 while the answer is…